Introduction to AI Engineering
Why it matters if you work with SQL and databases: LLMs, APIs, agents and evaluation: the complete frame, with a module on RAG, embeddings and vector databases that sets pgvector next to the dedicated engines.
If you work with SQL, databases or data pipelines, you are already at the centre of AI systems, even if you have never written a prompt. RAG means retrieval over your data, vector search has entered PostgreSQL through pgvector, agents query databases through MCP tools, and evaluating a model starts with a clean golden dataset. Your relevance does not depend on learning machine learning, but on understanding how models consume data and what makes them give wrong answers.
In the order in which they matter, each with the reason it matters if you work with SQL and databases. Untick what you already know: the subscription and the price update.
What an LLM is, how you talk to it, and the data engineering underneath every serious AI system.
Why it matters if you work with SQL and databases: LLMs, APIs, agents and evaluation: the complete frame, with a module on RAG, embeddings and vector databases that sets pgvector next to the dedicated engines.
Why it matters if you work with SQL and databases: Prompt engineering for code, including a case study on optimising a slow SQL query, and prompt security: instructions that produce verifiable output and resist injection.
Why it matters if you work with SQL and databases: The course written for you: ingestion with change data capture, ETL and ELT with Airflow, Dagster and dbt, Parquet and Iceberg, data quality and contracts, embedding pipelines and vector databases in depth, with Python and SQL throughout.
The central skill: correct retrieval, with permissions, over relational data and documents.
Why it matters if you work with SQL and databases: Chunking, embedding models, hybrid search, re-ranking, advanced architectures and systematic evaluation: the pipeline of any AI system that answers from your data, with pgvector among the vector stores it covers.
Why it matters if you work with SQL and databases: Retrieval strategies for context, vector, graph, relational and hybrid, plus persistent memory and compaction: where data modelling decides the quality of an agent.
Why it matters if you work with SQL and databases: How data is exposed to agents: the schema as a read-only resource, the query as a parameterized tool, with validation against SQL injection, authentication and least-privilege permissions. The practical projects include a PostgreSQL server.
Why it matters if you work with SQL and databases: Postgres with pgvector as the product database, and multi-tenant isolation built on one rule: every row that belongs to a tenant carries a tenant id, and every query filters on it.
The stage where your data becomes the basis for the quality, compliance and safety of the AI system.
Why it matters if you work with SQL and databases: Golden datasets with edge cases and slices, human annotation, RAG metrics with Ragas and regression tests in CI/CD, with attention to privacy for evaluation data: evaluation as a data discipline.
Why it matters if you work with SQL and databases: Data and feature management with feature stores, training pipelines, data lineage and drift monitoring: the pipeline in which your data feeds and monitors models.
Why it matters if you work with SQL and databases: PII, leakage and poisoning, the insecure handling of model output such as generated SQL, and the security of RAG pipelines: the requirements the data team will be asked to meet.
Not sure what you can skip? Take the free level assessment
It opens next to the lesson and starts from it. You type or talk to it, and you can listen to the answer.
Included in every plan and in single-course access, within a fair-use limit. It is an artificial intelligence system, not a human teacher; its answers may contain errors. Details in the Terms.
The professor opens next to the lesson, on the section you have reached, with four ways to start: a summary, applying it to your job, mistakes to avoid, or a test.
You select a passage and ask for an explanation. The answer starts from the lesson, and you can listen to it, copy it or save it to your notes.
The ideas of the lesson, point by point, when you ask for them. You can listen to the summary or send it to your notes.
3, 5 or 10 new questions from the lesson you are reading, with an explanation for every answer.
Flashcards made from the lesson: you flip the card and mark what you already knew.

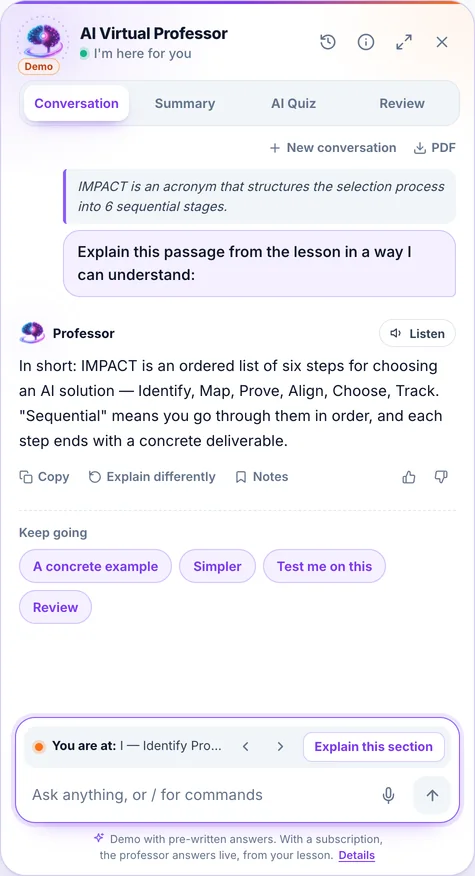
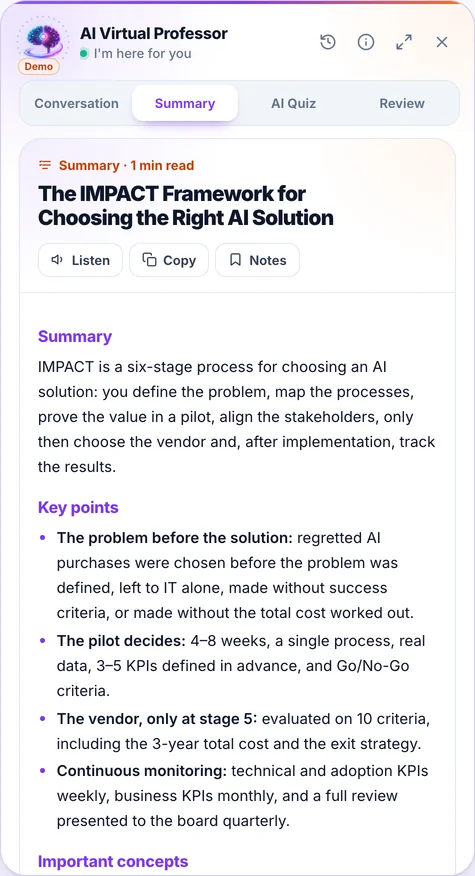
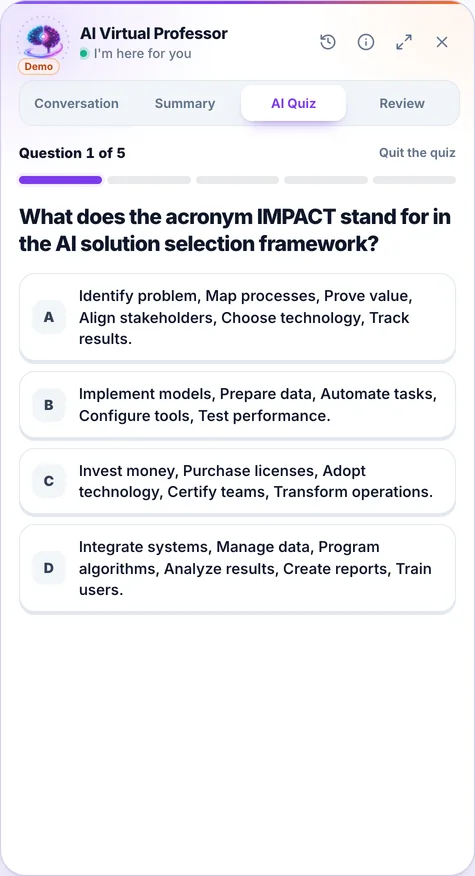
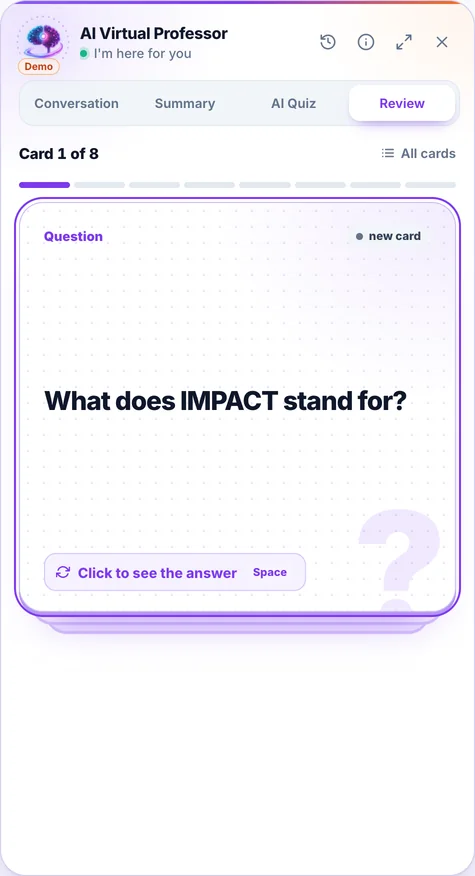
Screenshots from the app, taken in the demo lesson, with prepared answers.
The position of the language, what changes in your work, the tools and what you will be able to do at the end.
AI projects that fail in production very often fail on data: badly indexed documents, permissions ignored at retrieval, schemas the model does not understand, evaluation sets that do not reflect reality. Someone who knows data modelling, data quality and controlled access solves exactly these problems, provided they also understand the other half: embeddings, chunking, hybrid search, structured outputs, evals.
At the same time, models now generate queries, which changes who writes SQL. The need for SQL does not disappear; the monopoly on it does. Value moves towards designing schemas that models can use, validating what they generate and governing access: skills the courses below build on your foundation.
Chunking, embeddings, vector indexing, hybrid filtering and permissions at row or document level. A RAG pipeline is, in essence, a data pipeline with a model stage at the end.
Generated queries reach products. The AI security course treats model output sent to a database as untrusted input, so clear schemas, parameterization, least-privilege access and validation before execution become the data team’s job.
MCP servers for databases give agents access to schemas and queries. Least-privilege permissions, read-only resources, limits and audit are new requirements for whoever administers the data.
Golden datasets, human annotation, retrieval metrics and privacy rules for evaluation data. Evaluating AI systems is, to a large extent, data work done rigorously.
These are the skills you practise in the courses of the track; results depend on the time you invest and on your previous experience.
Start the SQL and databases trackThe whole SQL and databases track fits in a subscription of 10 courses: €319 a month, VAT included. You pick the courses and can change them at every renewal.
Pay for the tier, then pick the courses in your account. You can change them at every renewal.
€99 a course
€99a month €990a year, 12 months of access
under €67 a course
€199a month €1,990a year, 12 months of access
under €52 a course
€259a month €2,590a year, 12 months of access
under €32 a course
€319a month €3,190a year, 12 months of access
under €24 a course
€359a month €3,590a year, 12 months of access
under €16 a course
€399a month €3,990a year, 12 months of access
under €10 a course, across all 50
€499a month €4,990a year, 12 months of access
Total prices, VAT included. Move up anytime and pay only the difference for the days left; move down at renewal. Renews automatically, you stop it anytime from your account; your progress and certificates stay.
Payments are processed by Stripe, a PCI DSS Level 1 certified provider, with 3-D Secure for payer authentication. The connection to this site is TLS-encrypted.
Compare all the subscriptions · The team library, priced per member · Give a month of access as a gift
When you finish the lessons of a course with an average of at least 70% on its quizzes, you issue the PDF certificate from your account, at no extra cost.
A private attestation of course completion. It is NOT a diploma or a state-recognised qualification under Romanian Laws 198/2023, 199/2023 or Government Ordinance 129/2000; employers may take it into account at their own discretion.

 Blog
What Is an AI Engineer? Role, Skills, and How to Become One in 2026
 Blog
Prompt Engineering in 2026: From Beginner to Pro
The same skills, seen from each ecosystem. The languages close to SQL and databases are highlighted.
Yes. The courses are chosen for the data side of AI systems: pipelines, retrieval, schemas, evaluation, controlled access. You need Python at reading level for the examples; the introduction to AI engineering gives you the frame for the rest.
The data engineering course uses Python and SQL throughout, including in its lesson on pgvector. The MCP course builds a PostgreSQL server and treats the query as a parameterized tool. The other courses use Python, with SQL appearing where a database is involved.
They change it. Models generate queries; someone has to design schemas they understand, validate what they produce, limit access and evaluate the results on known sets. Those are the skills the data engineering, MCP, security and evaluation courses build on your SQL foundation.
All the courses recommended here are IT courses. You pick them in a subscription by number of courses: usually 3, 5 or 10 courses a month for one language and stack; there are also 15 and 25 courses, a single course and the full catalog. You pick the courses and can change them at every renewal. The subscription renews automatically, and you can stop the renewal anytime from your account. Every price, VAT included, is shown below and on the pricing page. Every course has a free preview of its first lesson, readable without an account.
10 courses, ~251 hours, in a subscription of 10 courses: €319 per month, VAT included. You can change them at every renewal.
The courses are for educational purposes only: they are not professional advice, and completing them is not a diploma or a state-recognised qualification. The names of languages, tools and products belong to their owners and are mentioned for identification only. Details in the Terms & Conditions.
ChatGPT, OpenAI, Claude, Anthropic, Gemini, Google, Microsoft 365 Copilot, Cursor, Midjourney and the other product and company names mentioned are trademarks or trade names of their respective owners. Cursuri AI is an independent training provider and is not sponsored or endorsed by any of them; our membership in Anthropic's Claude for Startups program does not mean that Anthropic endorses our courses.